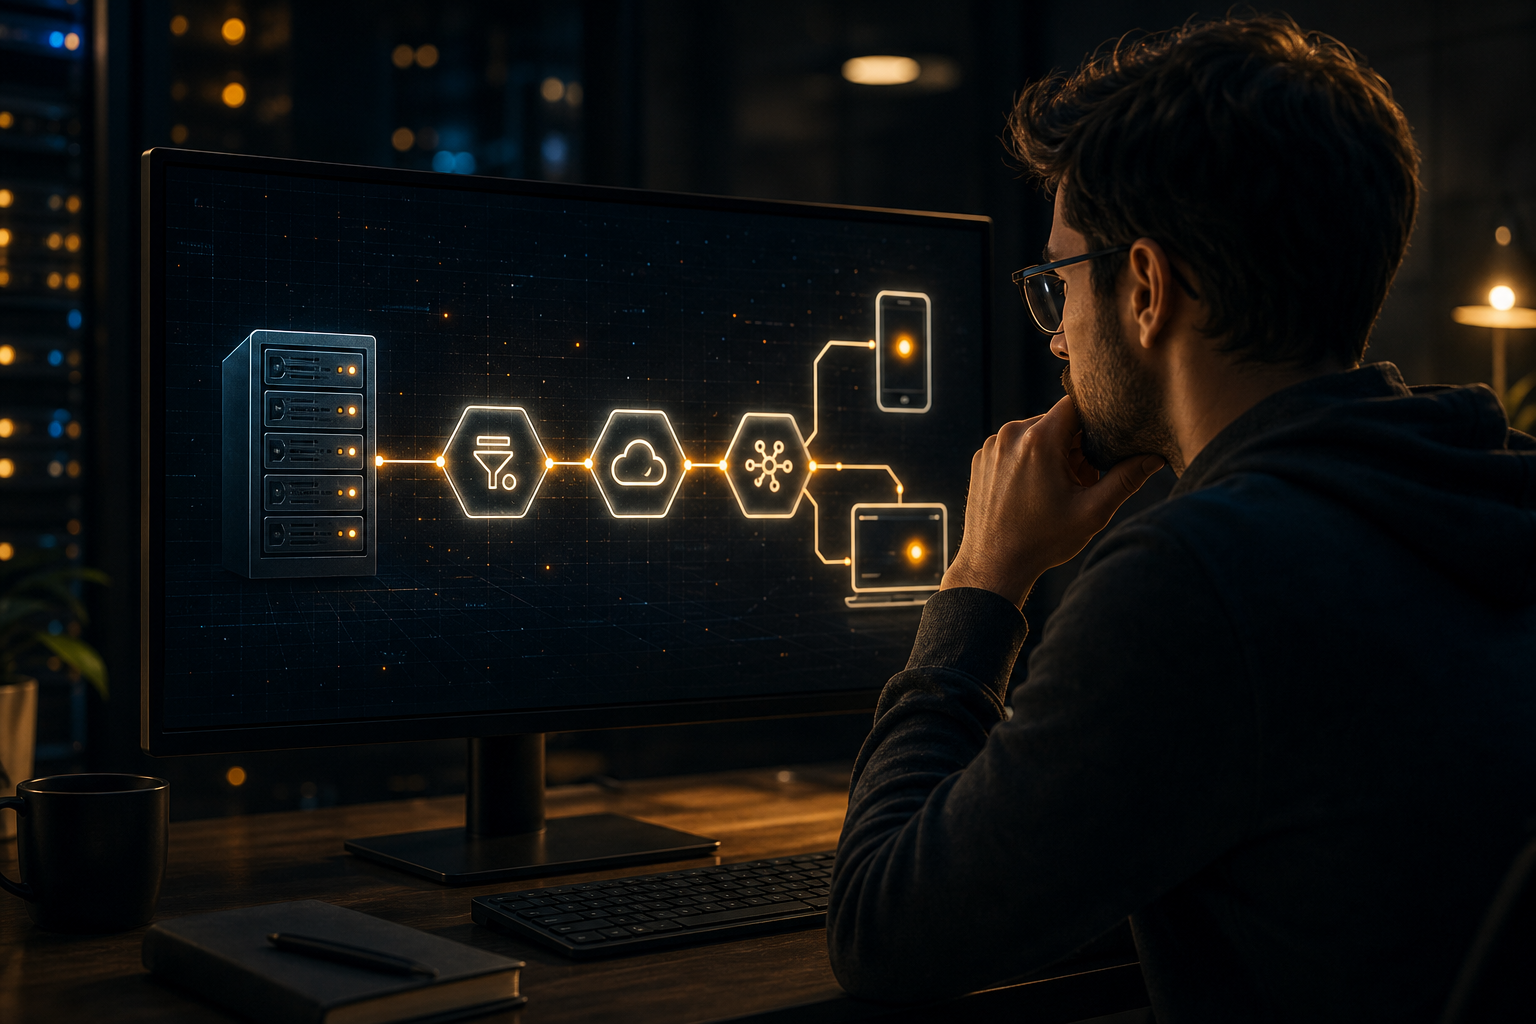
Push notifications fail in ways that are difficult to diagnose because the request crosses several systems. Your application may accept an event, the notification provider may accept a send, and the operating system may still refuse to display anything. A useful troubleshooting toolkit makes each stage observable and testable instead of treating “the notification did not arrive” as one problem.
This guide explains how to build that toolkit. It focuses on evidence, repeatable tests and clear failure boundaries, whether you operate your own delivery service or use a platform such as HoneyNotify.
Model the delivery path first
Before adding dashboards or retry logic, document the path a notification follows:
- An application event is created.
- Your server decides whether a notification should be sent.
- The server submits a request to the notification provider.
- The provider validates the request and queues or routes it.
- A device, user, tag, segment or other target is resolved.
- The platform-specific service receives the message.
- The operating system applies permission, policy and presentation rules.
- The client application receives, displays or processes the payload.
Each stage needs a distinct status. “Sent” should not mean “displayed”. At minimum, distinguish between application decision, request accepted, request rejected, provider delivery result, client receipt and user-visible presentation.
This model also tells you what evidence to collect. A server log cannot prove that an operating system displayed a notification, while a client log cannot explain why the server never attempted a send.
Build a searchable notification record
Create a notification record for every attempted send, including failures. Avoid logging sensitive payload content by default; store identifiers and selected diagnostic fields instead.
Useful fields include:
- A generated notification or operation ID.
- The application event ID that caused the send.
- The target type and a non-sensitive target reference.
- The provider request status and response category.
- The time of each state transition.
- An idempotency key or equivalent deduplication reference.
- The client platform and application environment, where known.
- A failure category and a safe, human-readable explanation.
If you use HoneyNotify for server-side sends, requests use POST /v1/notifications with a Bearer API key and an Idempotency-Key. A notification requires a title, body and target. Record the idempotency key alongside your internal operation ID so you can distinguish a retry from a new notification.
Do not use an access token, full device token or private payload as a general-purpose correlation ID. Redact secrets before logs are exported to a central system, and define retention rules for notification data.
Add a diagnostic mode
A troubleshooting toolkit should support controlled tests that do not depend on a real customer event. Build a small internal diagnostic flow with explicit inputs:
- A selected test user or device.
- A known application environment, such as development or production.
- A unique test correlation ID.
- A minimal title and body.
- A target type that is easy to verify.
Start with a single device target. It reduces ambiguity caused by audience membership, tag rules and segment calculation. Once that works, test user, tag, segment and broad targets separately.
Give diagnostic messages an unmistakable but safe marker in logs. Do not put secrets or personal data in the visible title or body. The diagnostic flow should show the complete state transition, including request creation, provider response and any client acknowledgement that your application supports.
A repeatable test is more valuable than repeatedly sending normal business notifications and guessing which component failed.
Verify registration and token lifecycle
Many delivery problems begin before the send. The client must register correctly, obtain a platform token, associate it with the intended identity and keep that association current.
Your toolkit should expose registration events such as:
- Permission requested, granted, denied or restricted.
- Token obtained, refreshed, invalidated or rejected.
- Device registration started, completed or failed.
- User identity attached, changed or removed.
- Application environment and platform recorded.
- Last successful client sync time.
Treat tokens as changeable credentials, not permanent device identities. Re-register when the operating system or provider supplies a new token, and make registration safe to repeat. A client should be able to recover after reinstalling the application, restoring a backup or changing permission without creating confusing duplicate state.
If you migrate from another provider, verify the identifier model carefully. Imported OneSignal subscription IDs can remain as device IDs when matching provider tokens later register, but token rotation or another provider environment can prevent matching. Your migration checks should therefore compare the actual provider token and environment, not only the imported identifier.
Separate authentication, validation and targeting failures
A failed request needs a category that points to an action. Broad labels such as “push error” are not enough.
Useful server-side categories include:
- Authentication: missing, malformed, expired or incorrectly scoped credentials.
- Request validation: missing title, body or target; invalid field types; unsupported values.
- Target resolution: unknown device, user with no enabled devices, empty tag or empty segment.
- Rate or quota handling: temporary refusal that may be retried according to provider guidance.
- Transport: timeout, connection failure or DNS problem before a definitive response.
- Provider processing: request accepted but later rejected or unable to reach the platform.
- Application policy: your own rules intentionally suppressed the send.
For HoneyNotify, verify that the request uses the required Bearer API key, includes an Idempotency-Key and supplies title, body and target. Check the target separately: a syntactically valid target can still resolve to no enabled devices.
Never retry every failure. Authentication and validation errors need correction. A timeout may justify a carefully bounded retry, but only with idempotency protection. Retrying a request after an unknown network outcome without deduplication can produce duplicate notifications.
Instrument the client SDK integration
Client-side diagnostics should be available without requiring a user to reproduce a problem while connected to a developer’s computer. Client SDKs commonly cover device registration, identity, token lifecycle, payload handling and lifecycle events across iOS, Android and Web Push. Your integration should expose those stages through structured, privacy-conscious logs.
Record events such as:
- SDK initialisation succeeded or failed.
- Permission state at the time of a send.
- Registration and token synchronisation status.
- Payload received in foreground, background or terminated states.
- Notification display decision made by the application.
- Deep-link or action handling result.
- Client-side exception or malformed payload handling.
Keep these events correlated with the server operation ID where possible. If the provider or SDK does not return that identifier to the client, include a short diagnostic value in a permitted data field, while ensuring that the field is not treated as trusted input.
Test each lifecycle state deliberately. A notification that appears while the application is open may follow different handling rules from one received while it is in the background. Web Push also depends on service-worker registration and browser permission, so test the service worker independently from the page UI.
Create a failure decision tree
Turn your observations into a short decision tree that support and engineering teams can use consistently.
- Was an application event created? If not, investigate business logic, queues or event ingestion.
- Did the notification service decide to send? If not, inspect suppression and targeting rules.
- Was a request submitted? If not, inspect worker health, credentials and transport.
- Was the request accepted? If not, classify authentication, validation or target errors.
- Did the target resolve to an enabled device? If not, inspect registration, identity and token state.
- Did the provider report a later delivery failure? If so, inspect platform credentials, environment and token validity.
- Did the client receive the payload? If not, inspect token matching, permissions, platform state and provider feedback.
- Did the client receive but not display it? Inspect payload handling, application state and operating-system presentation rules.
This prevents teams from jumping straight to client debugging when no request was sent, or changing payload fields when the real issue is an expired token.
Common mistakes
Several troubleshooting approaches create more noise than insight.
- Testing only with broad audience targets, which hides whether the target is resolvable.
- Treating an HTTP success response as proof of display.
- Logging only the final error and discarding request and client context.
- Retrying without an idempotency key or bounded backoff.
- Assuming a token never changes after first registration.
- Mixing development and production credentials, tokens or application identifiers.
- Changing several components at once, making the successful fix impossible to identify.
- Sending sensitive user data in test titles, bodies or diagnostic logs.
- Ignoring permission and notification-channel settings on the device.
- Failing to test foreground, background and terminated application states.
Use a controlled test matrix instead: one known device, one environment, one target type and one payload change at a time.
Make the toolkit operational
A toolkit is useful only if people can use it during an incident. Provide a small internal view or command that answers three questions quickly: what happened, where did it stop, and what should happen next?
Alert on patterns rather than isolated events. Examples include a sudden rise in authentication failures, a growing proportion of unresolved targets, registration failures after a client release, or a gap between provider acceptance and client receipt. Set thresholds from your own normal behaviour rather than copying figures from another system.
Document ownership for each boundary. The application team may own event creation, the platform team may own credentials and workers, and the mobile or web team may own registration and presentation. A shared failure taxonomy keeps those teams from reporting incompatible statuses.
Conclusion
Reliable push troubleshooting comes from tracing the complete path, not from adding more retries. Record a correlation ID for every attempt, separate acceptance from delivery and display, monitor token and permission state, and provide a controlled single-device diagnostic flow. With those foundations, push failures become bounded engineering problems: a missing event, a rejected request, an unresolved target, a stale registration or a client presentation issue.